Learning Low-Latency
Action Verification

for Frozen Vision-Language-Action Models

A tiny verifier, trained on the policy's own successes and failures, picks the better of two sampled actions. No VLA fine-tuning.

Wen-Han Hsieh1, Ken Jiankun Zheng1, Chia-Chien Chen2, David M. Chan1, Trevor Darrell1
1UC Berkeley  ·  2National Tsing Hua University
HDH (ours) · π0.5-DROID
01 / 06
Plushie onto plateFranka · 2× · 00:00 real time
0%
real-world success, from 44.7%
0%
LIBERO-10 success, from 78.8%
+0%
median latency overhead
0×
faster than a GPT-6 verifier
Overview

Let the policy's own rollouts decide which action to execute.

A compact verifier, trained on the outcomes of the frozen policy's own rollouts, chooses between two sampled action chunks at every query.

Read the abstract

Vision-language-action (VLA) models have made significant progress in general-purpose robotic manipulation. However, sampled action sequences can be ineffective, while evaluating alternatives with computationally expensive verifiers adds latency at each policy query. In this work, we propose HDH, a lightweight framework that uses hindsight from a frozen VLA's own deployments to improve action verification. The framework has three stages. First, we deploy the policy and collect its autonomous rollouts. We then train a compact action verifier to assign each action chunk a predicted task-success score. Finally, the frozen VLA generates action candidates, and the verifier selects the candidate with the highest score for execution. Across four LIBERO-10 tasks, HDH achieves an average success rate of 82.3% and on three real-world manipulation tasks, HDH improves average success over the baseline policy by 22.6%.
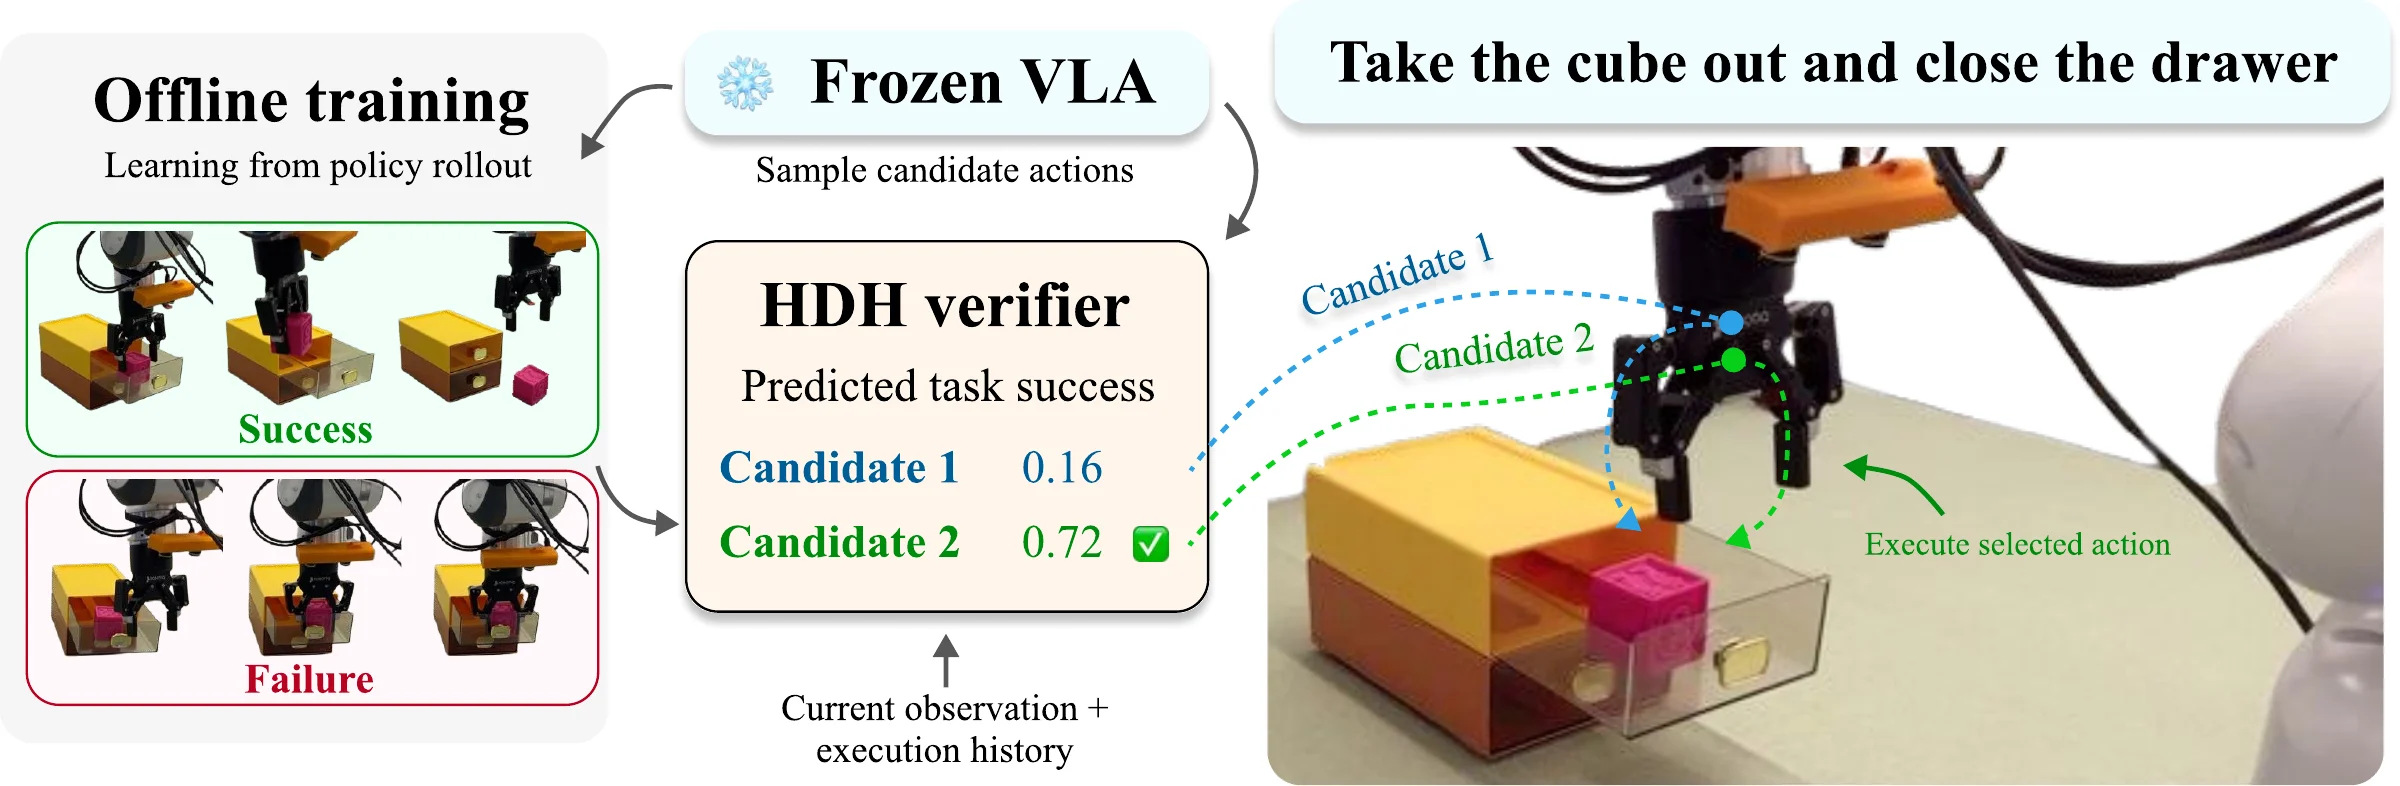
HDH overview: offline training on success and failure rollouts, a frozen VLA samples candidates, the HDH verifier scores them, and the robot executes the selected action.

Train on rollout outcomes (left), score sampled candidates (center), execute the best one (right).
Real Robot

HDH raises real-world success from 44.7% to 67.3%.

Franka Panda with π0.5-DROID. 50 trials per task and method.

OursHDH · K = 2
101/150
67.3% average success
Baselinefrozen π0.5-DROID · K = 1
67/150
44.7% average success
Largest gainPlushie onto plate
+30 pts
64% → 94%

Unedited episodes at 2×, failures included.

Method

Learn from outcomes, then choose among samples.

The VLA is never updated.

Stage 01

Collect

Roll out the frozen policy and record success or failure.

Stage 02

Train

Label every query with its episode's outcome and train a compact verifier.

Stage 03

Select

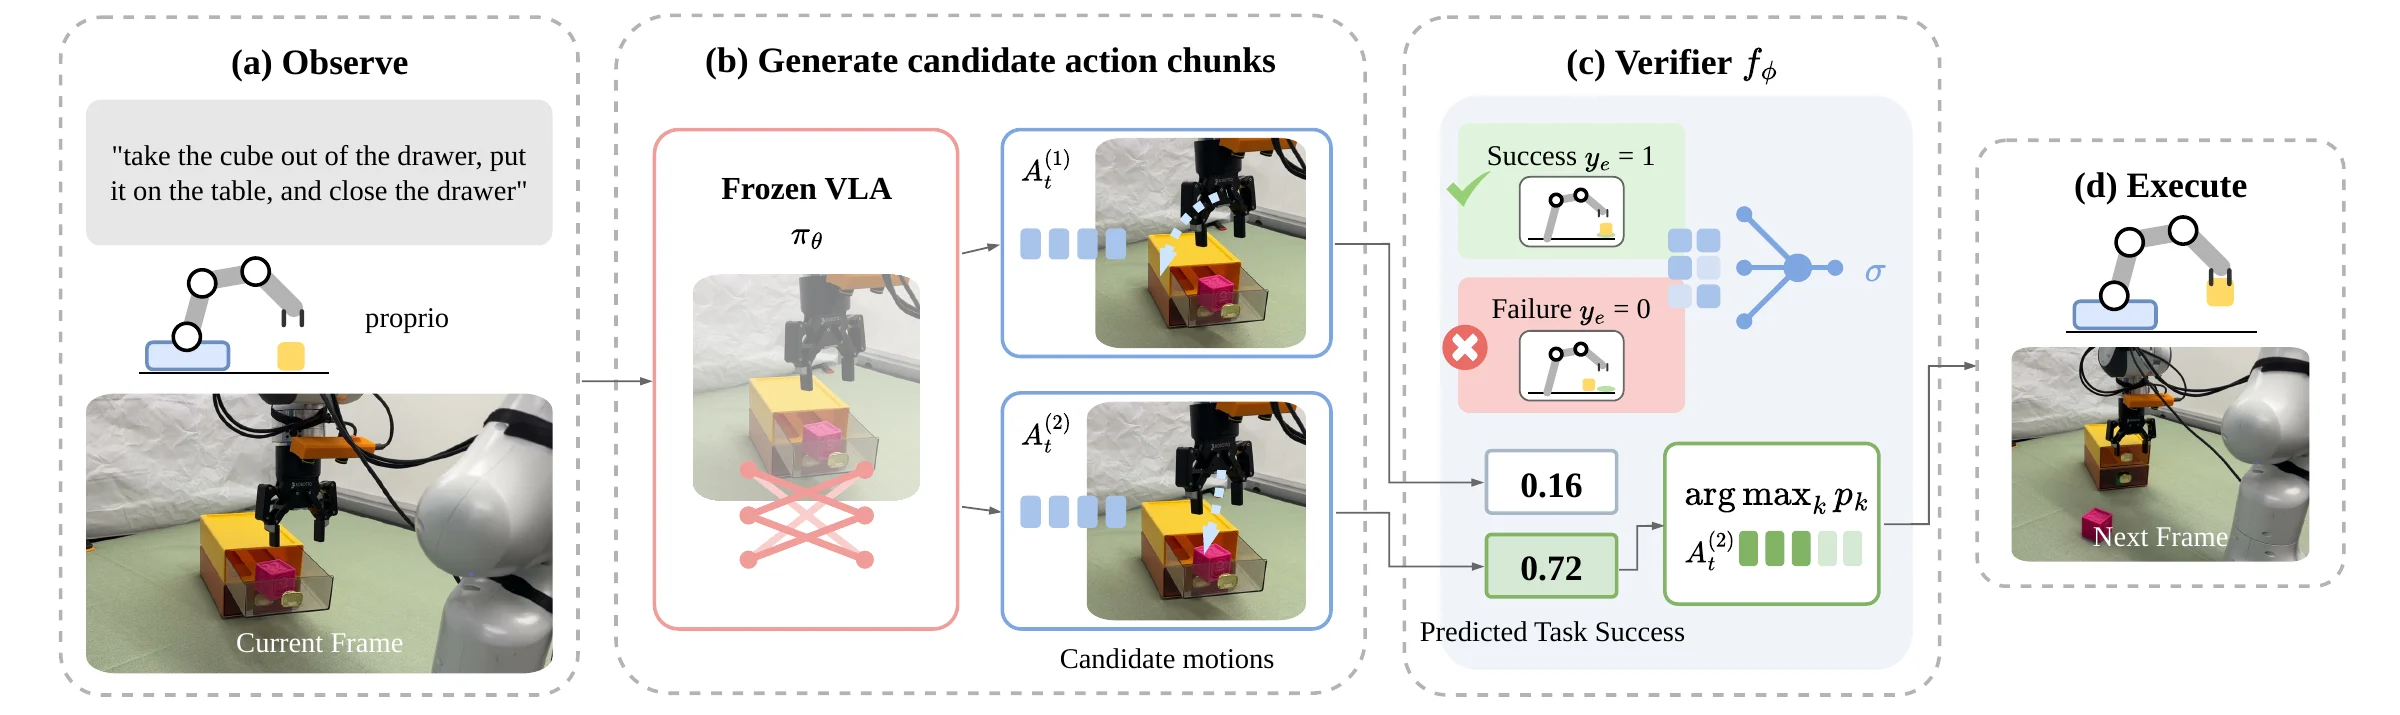
Sample two action chunks and execute 8 actions of the higher-scoring one.

HDH action selection: inputs, sampled candidates from a frozen VLA, verifier scoring, and execution of the selected prefix.

(a) Observe, (b) sample candidates from the frozen VLA, (c) score them, (d) execute the best.

Simulation

82.3% on LIBERO-10 at near-baseline latency.

Same frozen π0.5 for all methods. 50 held-out states × 3 runs per task.

Accuracy vs. latency

Median time per query, log scale.

learnedVLM verifierno verifier

Average success

Mean over four tasks (axis from 70%).

History helps: HDM 80.3% → HDH 82.3%.
MethodSoup + SauceBowl + DrawerMug + PuddingSoup + CheeseAveragep50 (ms)p95 (ms)
Baseline73.3 ± 2.596.0 ± 0.066.0 ± 2.880.0 ± 4.378.8681760
Random64.0 ± 2.895.3 ± 0.966.7 ± 6.684.0 ± 4.977.5692776
GPT-5†73.393.373.373.378.327,67446,911
GPT-669.3 ± 6.696.7 ± 0.972.0 ± 7.584.7 ± 2.580.77,40310,270
HDM70.0 ± 3.398.7 ± 0.966.7 ± 8.486.0 ± 4.380.3716799
HDH (Ours)76.7 ± 2.597.3 ± 2.572.0 ± 5.983.3 ± 5.082.3718796

Success (%), mean ± std over three runs. †15 states, one run.

Soup + Sauce into Basket
HDH 76.7% · baseline 73.3%
Bowl into Drawer + Close
HDH 97.3% · baseline 96.0%
Mug on Plate + Pudding to Right
HDH 72.0% · baseline 66.0%
Soup + Cheese into Basket
HDH 83.3% · baseline 80.0%
Citation

BibTeX

@article{hsieh2026hdh,
  title   = {Learning Low-Latency Action Verification for Frozen Vision-Language-Action Models},
  author  = {Hsieh, Wen-Han and Zheng, Ken Jiankun and Chen, Chia-Chien and Chan, David M. and Darrell, Trevor},
  journal = {arXiv preprint arXiv:2611.14834},
  year    = {2026}
}

Built on openpi, DROID and LIBERO. Page design follows rpg-robot.github.io.